Website Uptime Monitoring: What to Measure and Alert On
Uptime monitoring answers a deceptively simple question: can users reach the service? A single successful homepage request does not prove that a website is healthy. The homepage may load while checkout is broken, email is failing, or the database is approaching a resource limit. Useful monitoring combines external checks with application and infrastructure signals.
Availability Checks
An HTTP check requests a URL and evaluates the response. A basic check may look for a successful status code, while a stronger check verifies expected content or a known response marker. Use more than one endpoint when different parts of the application matter.
| Check | What it can reveal | Limitation |
|---|---|---|
| HTTP status | Whether a URL responds with an expected status | A 200 page can still be functionally broken |
| Content assertion | Whether expected text or a marker is present | Does not validate every user workflow |
| DNS lookup | Whether records resolve as expected | Does not prove the web service works |
| TLS certificate check | Certificate validity and expiration | Does not test application behavior |
| Transaction check | Whether a key workflow completes | Requires careful test accounts and safe data |
Monitor From Outside the Hosting Server
A monitoring agent running only on the same server may report that the site is healthy even when visitors cannot reach it through the network. External checks test the path from a separate location and can reveal DNS, routing, firewall, or edge problems.
For critical services, consider checks from multiple regions. A single monitoring location can itself experience a network issue and produce a false alarm.
Measure More Than Uptime
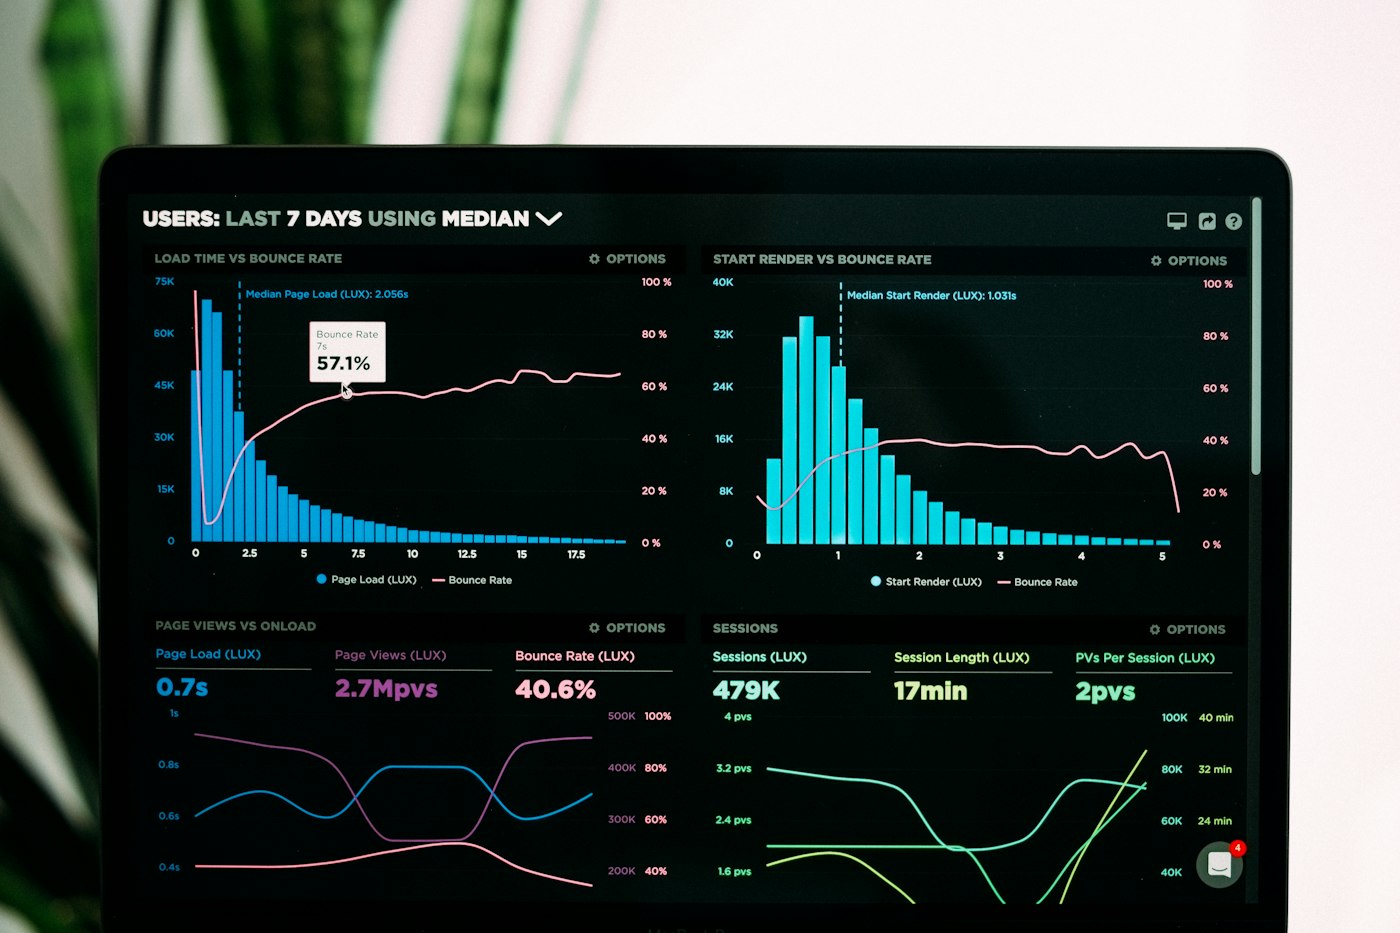
Response time matters because a service can technically be available while being unusably slow. Track latency over time and distinguish the time to first byte from full page rendering when your tooling supports it. For applications with important transactions, monitor the transaction rather than relying only on a static page.
Infrastructure metrics such as CPU, memory, disk space, process counts, and database connections can help explain a problem before it becomes a complete outage. They are diagnostic signals, not direct measures of user experience.
Design Alerts People Can Act On
An alert should identify the affected service, when the failure began, the observed symptom, and where to investigate. Avoid sending an alert for every failed probe. A common approach is to require consecutive failures or confirmation from another monitoring location before declaring an outage.
- Alert on sustained failures, not a single transient timeout.
- Use separate thresholds for warning and critical conditions.
- Route alerts to someone responsible for responding.
- Include links to relevant dashboards and runbooks.
- Review alerts that repeatedly fire without requiring action.
Understand False Positives and False Negatives
A false positive reports a failure when the service is actually available, perhaps because the monitoring provider had a network issue. A false negative occurs when the check passes while a critical function is broken. Using a static page alone can create false confidence; using an overly complex transaction can create fragile checks.
Keep Monitoring Credentials Safe
Transaction checks may need test credentials. Use dedicated accounts with limited privileges and avoid real payment methods or destructive operations. Store secrets in the monitoring platform’s secure configuration rather than embedding them in public URLs or scripts.
Build a Useful Incident Timeline
When an alert fires, record the first failed check, recovery time, relevant deployments, and changes to DNS or hosting configuration. Correlating monitoring with application logs helps distinguish a provider outage from an application regression.
Review the Monitoring Setup
- List the user journeys that matter most.
- Create external checks for the website and critical endpoints.
- Monitor DNS and TLS expiration separately.
- Set thresholds that account for transient failures.
- Test alert delivery and escalation.
- Review results after every significant application change.
Choose Check Intervals With the Response Plan in Mind
Very frequent checks can detect short outages quickly, but they may also produce more transient failures and consume monitoring quotas. Longer intervals reduce noise but delay detection. Choose an interval based on the service’s impact and the time someone needs to respond. For a low-impact brochure site, a modest interval may be enough; a transactional service may justify tighter coverage.
Define maintenance windows and alert suppression carefully. Suppression should prevent expected maintenance noise, not hide an outage that continues after the window ends.
Distinguish Availability From Performance
Set separate thresholds for a failed response and a slow response. A service that returns a page in 8 seconds may be technically available but still be unusable for customers. Use latency percentiles where available rather than relying only on a single average, because averages can conceal a smaller set of very slow requests.
Test the Alert Path
A monitoring system is incomplete until its notifications reach the right person. Send test alerts, verify on-call routing, and make sure escalation works when the first recipient does not acknowledge the incident. Review the contact list when staff or responsibilities change.
Document What Happens After an Alert
Create a short runbook for each critical check. Include the affected URL, expected response, log locations, recent deployment history, and the first safe diagnostic steps. The runbook should help an administrator distinguish a DNS issue, TLS failure, application error, and hosting resource problem without making risky changes under pressure.
Final Thoughts
Monitoring is useful when it detects real user impact and gives someone enough context to respond. Start with a few meaningful checks, make alerts actionable, and expand coverage as the application becomes more complex.